8 Best Business Continuity Strategies for SMEs
A ransomware alert at 9:15 a.m., an internet outage before payroll, or a failed server during a client deadline can stop a small business faster than most leaders expect. The best business continuity strategies are not a binder stored in a cabinet. They are practical decisions about which systems must keep running, how quickly they must recover, and who takes action when normal operations fail.
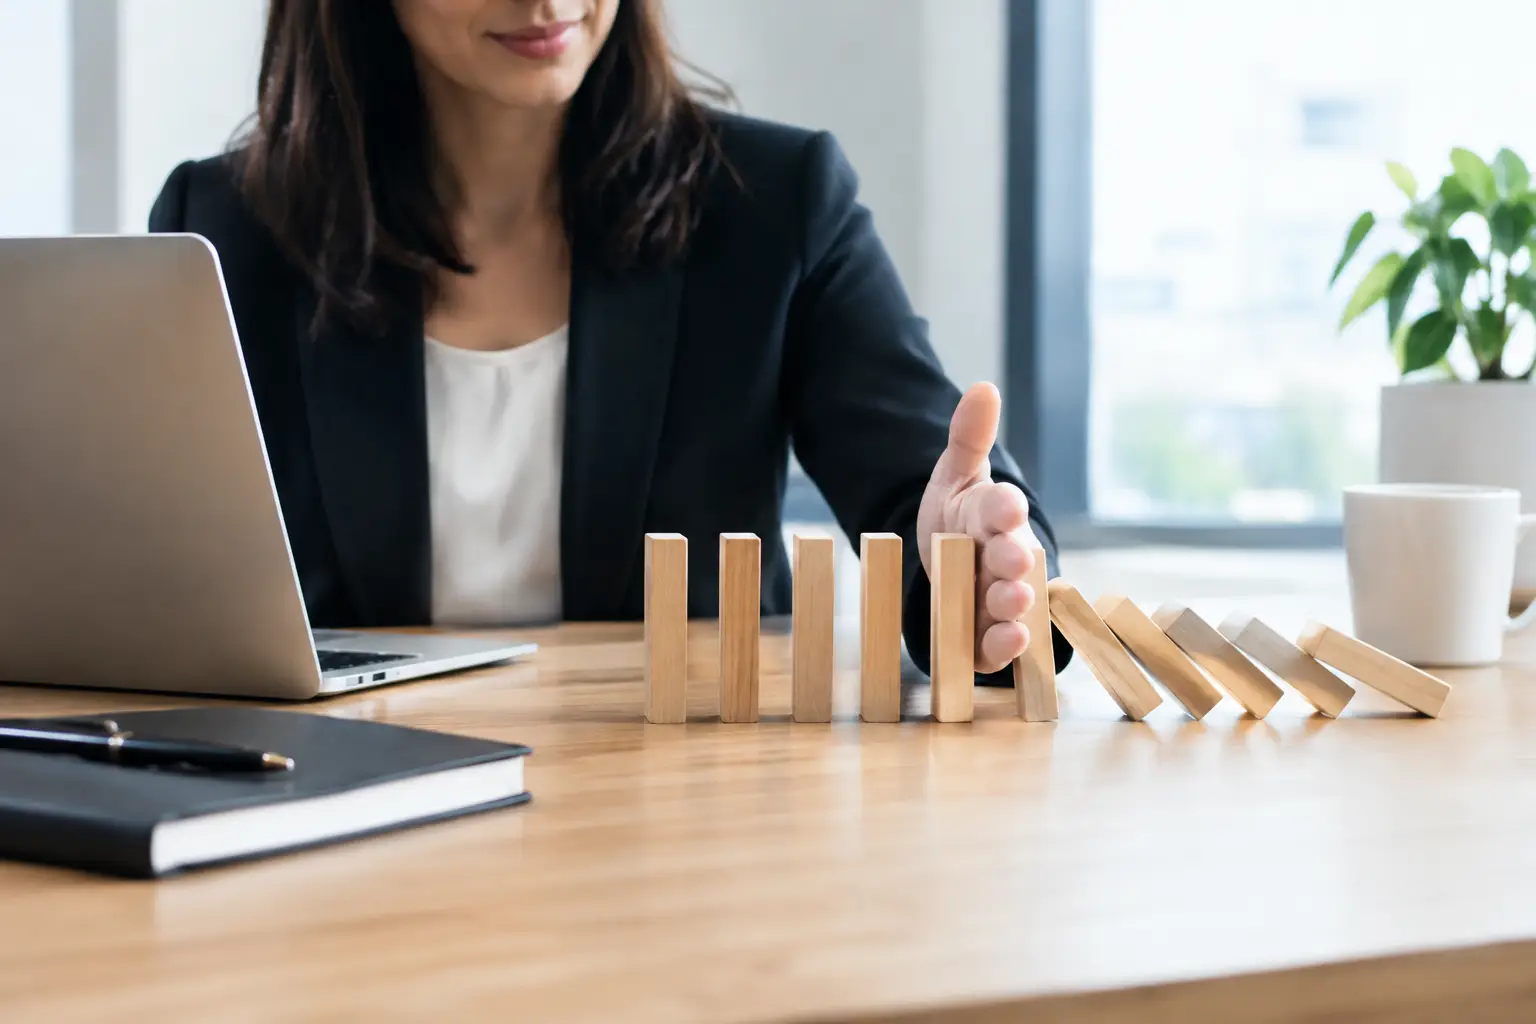
For small and midsize businesses, continuity planning is a business protection measure, not an enterprise-only project. A few hours of downtime can mean missed revenue, delayed service, regulatory exposure, overtime costs, and damaged customer confidence. The goal is simple: reduce disruption, restore priority operations quickly, and prevent a single technology issue from becoming a company-wide crisis.
Start With Business Impact, Not Technology
Continuity plans fail when they begin with a list of devices rather than the work those devices support. A cloud application may be less critical than a phone system for one company, while another cannot process orders without it. The right priorities depend on how your business earns revenue, serves customers, meets contractual obligations, and protects sensitive information.
Identify the processes that cannot be paused for long. This could include customer communications, dispatch, payment processing, access to accounting records, electronic health records, document management, or remote access for a hybrid team. Then map the people, vendors, applications, internet connections, and data behind each process.
Set Recovery Targets Leaders Can Approve
Two measurements turn a broad plan into an operating standard. Recovery time objective, or RTO, defines how long a service can be unavailable. Recovery point objective, or RPO, defines how much data the business can afford to lose.
For example, a company might decide that its customer-facing phone system must be restored within one hour, while a file archive can wait until the next business day. It may accept losing no more than 15 minutes of transaction data but tolerate a 24-hour recovery point for older records. These are business decisions with technical consequences. Faster recovery usually requires greater investment in backup frequency, redundancy, monitoring, and support coverage.
8 Best Business Continuity Strategies That Work
1. Build a Clear, Role-Based Response Plan
During an outage, vague instructions create costly delays. Your plan should name who declares an incident, who contacts employees and customers, who works with vendors, and who can authorize emergency spending or operational workarounds.
Keep the plan short enough to use under pressure. Include current contact details, escalation paths, system recovery priorities, key vendor information, and step-by-step instructions for common scenarios such as ransomware, internet failure, power loss, or a Microsoft 365 access issue. Store a protected offline copy as well as a cloud-based copy. A plan available only through the systems that are down is not a plan.
2. Protect Data With Tested, Isolated Backups
Backup completion messages do not prove recoverability. Files can be corrupted, encryption can spread before it is detected, and a backup account can be compromised alongside the production environment.
Use multiple backup copies, keep at least one copy isolated from everyday network access, and retain versions long enough to recover from a delayed discovery of ransomware or accidental deletion. Critical servers, cloud data, configurations, and line-of-business applications all need coverage. Just as important, run scheduled restore tests. Measure how long restoration takes and confirm that recovered data is usable by the people who need it.
3. Treat Cybersecurity as a Continuity Control
Many business interruptions begin with a security event. Phishing, stolen credentials, unpatched systems, and poorly secured remote access can turn a normal workday into a recovery effort.
Layered protection reduces the chance that one mistake stops the operation. Multi-factor authentication, endpoint protection, email filtering, least-privilege access, security awareness training, and timely patching each address a different failure point. Your incident response plan should also state when to isolate a device, disable an account, preserve evidence, contact cyber insurance, and notify legal or compliance stakeholders. Speed matters, but uncoordinated action can destroy evidence or extend downtime.
4. Remove Single Points of Failure Where They Matter Most
Not every system needs duplicate hardware or a second internet circuit. Investing in redundancy everywhere can waste budget that would better protect higher-risk operations. Focus on failures with the greatest business impact.
For a company dependent on cloud calling and online transactions, a secondary internet connection or cellular failover may be justified. For a business with on-premises servers supporting critical applications, redundant storage, power protection, and a documented failover option may be appropriate. The right design is based on the RTO and RPO you set, not on a one-size-fits-all technology checklist.
5. Monitor Systems Before Users Report the Problem
Reactive support begins when employees call because something is slow or unavailable. Proactive continuity begins with visibility into device health, storage capacity, backup status, patch compliance, login activity, network performance, and security alerts.
Continuous monitoring gives your technology team time to address an expiring certificate, failed backup job, overloaded server, or unstable network device before it interrupts staff or customers. It also creates a clearer record of what happened during an incident. For growing businesses, remote monitoring and management can provide this discipline without building a large internal IT department.
6. Plan for Communication When Normal Channels Fail
Customers are more forgiving of a disruption than of silence. Employees also need a reliable source of direction when email, phones, or core applications are unavailable.
Prepare message templates for staff, clients, vendors, and leadership. Define who can speak externally, what information can be shared, and how often updates will be provided. Maintain alternate communication options, such as a designated mobile contact list or approved emergency messaging channel. Be honest about the issue without speculating. A clear update that says service is affected, the team is responding, and the next update will arrive at a specific time builds more trust than an overly detailed explanation that later proves incorrect.
7. Keep Vendor Dependencies in the Plan
Your operations may depend on more than your own network. Internet providers, cloud platforms, payment processors, hosted phone systems, software vendors, building access systems, and managed service partners can all affect recovery time.
Document support numbers, account identifiers, escalation procedures, service-level commitments, and alternative options for critical vendors. Review contracts to understand what recovery assistance is included and what falls on your organization. If a vendor outage would prevent billing, shipping, or customer service, establish a manual process in advance. It may not be efficient, but it can protect revenue while technology is restored.
8. Test the Plan and Improve It After Every Incident
A continuity plan becomes reliable through practice. Start with tabletop exercises that walk leadership and department owners through a realistic scenario. Ask direct questions: Who notices the event first? Who has authority to shut down access? Can staff work remotely? How are customers notified? Where is the latest backup recovery procedure?
Then test technical recovery in controlled conditions. Restore a critical file, recover a virtual server, test internet failover, or simulate loss of an employee account. Document the gaps, assign owners, and set deadlines for fixes. Real incidents should receive the same review. The objective is not to assign blame. It is to improve response time, eliminate recurring weaknesses, and make the next disruption less damaging.
Make Continuity an Ongoing Operating Discipline
Business continuity changes as your company changes. A new location, acquired business, remote workforce, cloud migration, compliance requirement, or new payment platform can alter the systems and risks that matter most. Review priorities at least annually and after any significant operational or technology change.
For businesses in Deerfield Beach and across South Florida, hurricanes and utility disruptions add another reason to plan beyond cyber threats. But the same preparation supports nearly every incident: current backups, documented recovery steps, secure remote access, clear communications, and a team that knows its role.
Krove helps businesses turn continuity from a last-minute reaction into a managed process through proactive monitoring, cybersecurity, backup management, disaster recovery planning, and responsive support. The most useful next step is not buying more technology. It is identifying the one interruption your business cannot afford and confirming, with evidence, how you would recover from it.